Overview
Mergeway’s goal is to make metadata a commodity putting it in the open and treating it as code. Instead of juggling spreadsheets or custom scripts, you describe entities in YAML/JSON, run a quick validation, and catch broken references before they reach production. By storing metadata as code, changes become a simple patch.
What the CLI Does
- Stores entity definitions and relationships in version-controlled files.
- Validates schemas and records so required fields and references stay consistent.
- Generates simple reports you can attach to pull requests or issues.
Key Features
- Workspace scaffolding:
mergeway-cli initwrites a startermergeway.yamlinto your working directory so you can begin defining entities immediately. - Dual schema sources: Author entity fields inline in YAML or reference existing JSON Schema documents (
json_schema) so teams can reuse specs. - Object lifecycle commands:
list,get,create,update, anddeleteoperate on local YAML/JSON files, respecting schema-defined identifiers whether they come from record fields or the special$pathfile-path mode. - Deterministic formatting:
mergeway-cli fmtemits canonical structure and rewrites files in place (use--stdoutto preview changes) to keep diffs clean. - Layered validation: Format, schema, and reference phases catch structural, typing, and cross-entity errors before they land in main.
- Schema introspection:
mergeway-cli entity showandmergeway-cli config exportsurface normalized schemas or derived JSON Schema for documentation and automation.
Why Teams Use Mergeway
- Fast feedback: One command surfaces missing fields, enum mismatches, or invalid references.
- Git-native: Changes live in branches and pull requests, making reviews trivial.
- Lightweight: No server component—just a binary that runs locally or in CI.
Where to Go Next
- Install Mergeway (or build from source).
- Follow the Workspace set-up.
- Review the Basic Concepts and Schema Format when you define entities.
- Browse the binary references: mergeway-cli, mergeway-diff, mergeway-lsp, and mergeway-mcp.
Updates land in the Changelog. File GitHub issues for questions, bugs, or requests.
For a more general introduction to Mergeway, visit the homepage
Getting Started
This guide introduces the basic concepts and structure of a Mergeway workspace. It is intended for new users who want to understand how to set up and use Mergeway effectively. For runnable sample workspaces, see the examples directory in the GitHub repository.
If you need installation help first, start with Installation. If you are here for editor integration, continue with Run mergeway-lsp manually.
A Mergeway workspace is just a folder with a few predictable parts. Knowing the vocabulary makes the CLI output easier to read.
Building Blocks
- Workspace: Folder tracked in Git that contains
mergeway.yaml, schemas, and optional objects. All commands run from here. - Schema: YAML/JSON that defines fields and references. Each file describes one entity.
- Object: Optional data instances stored under
data/. - Reference: A link from one schema or field to another (
type: ref). Mergeway validates referential integrity.
Validation Flow
- Mergeway loads
mergeway.yamlto locate schemas and records. - Schemas are parsed and checked for required fields, types, and references.
- Records (if present) are validated against their schemas.
For field syntax and configuration options, see the Schema Format.
Installation
Use one of the installation paths below depending on whether you need only mergeway-cli or the wider toolset.
Option 1: Download a Release Archive
GitHub releases publish platform assets for:
- Linux, macOS, and Windows
amd64andarm64mergeway-cli,mergeway-diff,mergeway-lsp, andmergeway-mcp
Download the asset or assets for your platform from the latest release page, then install the extracted binaries you need:
install -m 0755 mergeway-cli /usr/local/bin/mergeway-cli
install -m 0755 mergeway-diff /usr/local/bin/mergeway-diff
install -m 0755 mergeway-lsp /usr/local/bin/mergeway-lsp
install -m 0755 mergeway-mcp /usr/local/bin/mergeway-mcp
Put mergeway-cli on PATH for terminal use, mergeway-diff on PATH for semantic snapshot workflows, mergeway-lsp on PATH for editor integration, and mergeway-mcp on PATH for MCP client integrations.
Option 2: Docker
The published container image is useful for CLI-only workflows:
docker run --rm ghcr.io/mergewayhq/mergeway-cli version
To run against the workspace in your current directory:
docker run --rm \
  -v "$PWD:/work" \
  ghcr.io/mergewayhq/mergeway-cli validate
The container image does not include mergeway-diff, mergeway-lsp, or mergeway-mcp.
Option 3: Go Install
go install github.com/mergewayhq/mergeway-cli@latest
This installs mergeway-cli. Install the other binaries separately if needed:
go install github.com/mergewayhq/mergeway-cli/cmd/mergeway-diff@latest
go install github.com/mergewayhq/mergeway-cli/cmd/mergeway-lsp@latest
go install github.com/mergewayhq/mergeway-cli/cmd/mergeway-mcp@latest
Option 4: Nix
Install the CLI with Nix:
nix profile install github:mergewayhq/mergeway-cli
Or run it directly:
nix run github:mergewayhq/mergeway-cli -- help
The flake path is currently oriented around the CLI. Use a release archive or a local source build if you also need mergeway-diff, mergeway-lsp, or mergeway-mcp.
Option 5: Build from Source
git clone https://github.com/mergewayhq/mergeway-cli.git
cd mergeway-cli
make build
./bin/mergeway-cli version
./bin/mergeway-diff --help
./bin/mergeway-lsp --log-stderr --log-level=debug
./bin/mergeway-mcp --help
make build produces all four binaries under bin/.
Supported Platforms
- Release archives support Linux, macOS, and Windows.
- Each release includes
amd64andarm64builds. - The container image is Linux-only and CLI-only.
Verify the Installation
mergeway-cli version
mergeway-diff --help
mergeway-lsp --log-stderr --log-level=debug
mergeway-mcp --help
If the language server starts successfully, it waits for LSP input on stdin. Stop it with Ctrl+C.
If the MCP server starts successfully in stdio mode, it waits for MCP traffic on stdin and reserves stdout for protocol messages. Stop it with Ctrl+C.
For manual startup and editor wiring, continue with Run mergeway-lsp manually.
Run mergeway-lsp manually
mergeway-lsp is a Language Server Protocol server that communicates over stdio. In normal use, your editor starts it for you and keeps stdout reserved for protocol traffic.
Install or Build the Binary
Use one of these paths:
- extract
mergeway-lspfrom a release archive - run
make buildand use./bin/mergeway-lsp
The published Docker image does not include the language server.
Start the Server Manually
If mergeway-lsp is on your PATH:
mergeway-lsp
From a local source checkout:
./bin/mergeway-lsp
The process will wait for framed LSP messages on stdin.
Enable Debug Logging
Use stderr logging while testing locally:
mergeway-lsp --log-stderr --log-level=debug
Or write logs to a file:
mergeway-lsp --log-file /tmp/mergeway-lsp.log --log-level=debug
Equivalent environment variables:
MERGEWAY_LSP_LOG_STDERR=1MERGEWAY_LSP_LOG_FILE=/tmp/mergeway-lsp.logMERGEWAY_LSP_LOG_LEVEL=debug
Keep stdout protocol-only. Human-readable logging on stdout will break editor integration.
For a concise flag and environment-variable reference, see mergeway-lsp.
Current Capabilities
- workspace-aware diagnostics backed by the same validation core as
mergeway-cli validate - completion for fields, entity references, and close enum values
- hover, go-to-definition, find references, document symbols, and workspace symbols
- conservative quick fixes for a small set of unambiguous schema and data mistakes
Current Limitations
- The VS Code extension still requires manual configuration of the local
mergeway-lspbinary path. - The server currently uses full-document sync.
- Missing-required-field quick fixes are limited to YAML and YML files.
- Features only apply to files owned by a detected Mergeway root.
For editor configuration examples, see Set up mergeway-lsp in VS Code and Neovim.
Workspace setup
Goal: scaffold a workspace, define an entity, evolve the layout as requirements grow, and learn the core Mergeway commands end-to-end.
All commands assume the
mergeway-clibinary is on yourPATH.
1. Scaffold a Workspace with Inline Data
mkdir farmers-market
cd farmers-market
mergeway-cli init
mergeway-cli init creates a mergeway.yaml entry file. Replace its contents with an inline entity that also carries a few inline records:
mergeway:
  version: 1

entities:
  Category:
    description: Simple lookup table for product groupings
    identifier: slug
    fields:
      slug:
        type: string
        required: true
      label:
        type: string
        required: true
    data:
      - slug: produce
        label: Fresh Produce
      - slug: pantry
        label: Pantry Staples
Try a few commands:
mergeway-cli entity list
mergeway-cli entity show Category
mergeway-cli list --type Category
mergeway-cli validate
At this stage everything lives in a single file—perfect for tiny datasets.
2. Move Records into External YAML Files
As the table grows, shift the data into dedicated files. Create a folder for category data and move the records there:
mkdir -p data/categories
cat <<'YAML' > data/categories/categories.yaml
items:
  - slug: produce
    label: Fresh Produce
  - slug: pantry
    label: Pantry Staples
  - slug: beverages
    label: Beverages
YAML
Update mergeway.yaml so Category reads from the new file:
mergeway:
  version: 1

entities:
  Category:
    description: Simple lookup table for product groupings
    identifier: slug
    include:
      - data/categories/*.yaml
    fields:
      slug:
        type: string
        required: true
      label:
        type: string
        required: true
Re-run the commands to see the effect:
mergeway-cli list --type Category
mergeway-cli get --type Category beverages
mergeway-cli validate
3. Split Schema Definitions and Add JSON Data
Larger workspaces benefit from keeping schemas in their own files. Create an entities/ folder for additional definitions:
mkdir -p entities
Add a new Product entity that pulls from a JSON file using a JSONPath selector:
cat <<'YAML' > entities/Product.yaml
mergeway:
  version: 1

entities:
  Product:
    description: Market products with category references
    identifier: sku
    include:
      - path: data/products.json
        selector: "$.items[*]"
    fields:
      sku:
        type: string
        required: true
      name:
        type: string
        required: true
      category:
        type: Category
        required: true
      price:
        type: number
        required: true
YAML
Create the JSON data file the schema expects. Notice that one product references a household category that we haven’t defined yet:
cat <<'JSON' > data/products.json
{
  "items": [
    {"sku": "apple-001", "name": "Honeycrisp Apple", "category": "produce", "price": 1.25},
    {"sku": "oat-500", "name": "Rolled Oats", "category": "pantry", "price": 4.99},
    {"sku": "soap-010", "name": "Castile Soap", "category": "household", "price": 6.75}
  ]
}
JSON
Finally, have mergeway.yaml pull in any external schemas:
mergeway:
  version: 1

include:
  - entities/*.yaml

entities:
  Category:
    description: Simple lookup table for product groupings
    identifier: slug
    include:
      - data/categories/*.yaml
    fields:
      slug:
        type: string
        required: true
      label:
        type: string
        required: true
Explore the richer workspace:
mergeway-cli entity list
mergeway-cli entity show Product
mergeway-cli list --type Product
mergeway-cli validate
mergeway-cli validate now reports a broken reference because the household category doesn’t exist yet:
phase: references
type: Product
id: soap-010
file: data/products.json
message: referenced Category "household" not found
Add the missing category to the YAML file and validate again:
cat <<'YAML' >> data/categories/categories.yaml
- slug: household
  label: Household Goods
YAML

mergeway-cli validate
With the additional category in place, validation succeeds and both entities are in sync.
4. Export Everything as JSON
Collect the full dataset into a single snapshot:
mergeway-cli export --format json --output market-snapshot.json
cat market-snapshot.json
Keep the Workflow Running Smoothly
Once the basics feel comfortable, automate formatting and reviews so the workspace stays healthy:
- Set Up Mergeway with GitHub to enforce
mergeway-cli fmt --lintin Actions and route reviews through CODEOWNERS. - Enforce Mergeway Formatting with pre-commit so contributors run
mergeway-cli fmtlocally before every commit.
You’re Done!
Nice work—you’ve defined entities inline, moved data to YAML, added JSON-backed entities, and exercised the key Mergeway commands. You’re ready to scale the workspace to your team’s needs.
Schema Format
Schemas can live entirely inside mergeway.yaml or be split across additional include files (for example under an entities/ folder) for readability. Likewise, object data may be defined inline or stored under data/. Pick the mix that matches your editing workflow—comments below highlight conventions for modular repositories without requiring them.
Configuration Entry (mergeway.yaml)
The workspace entry file declares the schema version and the files to load:
mergeway:
  version: 1

include:
  - entities/*.yaml
mergeway.versiontracks breaking changes in the configuration format (keep it at1).includeis a list of glob patterns. Each matching file is merged into the configuration. Patterns need to resolve to at least one file; otherwise Mergeway reports an error.
Schema Files (optional includes)
A schema file declares one or more entity definitions. Store them in whichever folder makes sense for your workflow (many teams use entities/); the location has no semantic impact. The example below defines a Post entity:
mergeway:
  version: 1

entities:
  Post:
    description: Blog posts surfaced on the marketing site
    extends: Content
    identifier: id
    include:
      - data/posts/*.yaml
    fields:
      id: string
      title:
        type: string
        required: true
        description: Human readable title
      body: string
      author:
        type: User
        required: true
    data:
      - id: post-inline
        title: Inline Example
        author: user-alice
        body: Inline data lives in the schema file.
For advanced scenarios you can expand identifier into a mapping:
mergeway:
  version: 1

entities:
  Post:
    description: Blog posts surfaced on the marketing site
    identifier:
      field: id
      generated: true
    include:
      - data/posts/*.yaml
    fields:
      # ...
generated: true is an advisory hint for downstream automation (code generators, UI scaffolding). The CLI still expects inline identifiers or an explicit --id flag when creating objects.
If you want the file path itself to be the identifier, use the reserved $path value:
mergeway:
  version: 1

entities:
  Note:
    identifier: $path
    include:
      - data/notes/*.yaml
    fields:
      title:
        type: string
        required: true
In that mode, Mergeway uses the workspace-relative path (for example data/notes/alpha.yaml) as the object ID. $path only works for one-object-per-file sources. Inline data, items: arrays, and selectors that return multiple objects from the same file are rejected because they would produce duplicate identifiers.
When several objects live in one file, provide a JSONPath selector to extract them:
mergeway:
  version: 1

entities:
  User:
    description: Directory of account holders sourced from JSON
    identifier: id
    include:
      - path: data/users.json
        selector: "$.users[*]"
    fields:
      # ...
Strings remain a shorthand for path with no selector; Mergeway then reads the entire file as a single object (or uses the items: array if present).
Inheritance
Entities may optionally declare extends to inherit from exactly one parent entity:
mergeway:
  version: 1

entities:
  Content:
    identifier: id
    fields:
      id: string
      title:
        type: string
        required: true
  Post:
    extends: Content
    identifier: id
    include:
      - data/posts/*.yaml
    fields:
      body: string
When inheritance is used:
- Base entities may be schema-only and can omit
includeand inlinedata. - Children inherit all parent fields and append child-defined fields after them.
- Children may not redefine inherited field names or the identifier definition.
- Identifier values must be unique across the whole parent/descendant hierarchy.
- Querying a parent entity includes descendant objects.
- References declared as
type: Parentaccept identifiers from the parent or any descendant.
extends only supports single inheritance. It is not supported for json_schema-backed entities in the first version.
See examples/inheritance for a runnable workspace that combines a schema-only base entity, inherited fields, parent queries, and parent-typed references to descendants.
Required Sections
| Key | Description |
|---|---|
identifier | Identifier source for each record. Provide either a string field name (for example id), the reserved $path value to use the workspace-relative file path, or a mapping with field, optional generated, and pattern. Field-based identifiers can be strings, integers, or numbers. $path identifiers are strings and require one object per file. The generated flag is advisory for tooling; the CLI still expects identifiers to be supplied inline or via --id when creating objects. |
extends | Optional parent entity name. Use this when the entity should inherit fields and identifier rules from one parent. Only single inheritance is supported, and extends cannot be combined with json_schema in the first version. |
include | List of data sources. Each entry can be a glob string (shorthand) or a mapping with path and optional selector property. Omit only when you rely exclusively on inline data, or when the entity is a schema-only base entity meant to be extended by children. Without a selector, Mergeway treats the whole file as a single object. |
fields | Map of field definitions. Use either the shorthand field: type (defaults to optional) or the expanded mapping for advanced options. Provide either fields or json_schema for each entity. |
json_schema | Path to a JSON Schema (draft 2020-12) file relative to the schema that declares the entity. When present, Mergeway derives field definitions from the JSON Schema and you can omit the fields block. extends is not supported on these entities in the first version. |
data | Optional array of inline records. Each entry needs to contain the identifier field and follows the same schema rules as external data files. This block cannot be used when identifier: $path because inline records do not have file paths. |
Fields can also declare a read-only source that derives values from the backing file path:
fields:
  section:
    type: string
    source:
      path_segment: 2
  filename:
    type: string
    source:
      path_segment_rev: 0
  relative_path:
    type: string
    source:
      path: true
Exactly one source selector may be set per field. path_segment counts from the workspace root downward, path_segment_rev counts backward from the filename, and path: true exposes the full normalized relative file path. These fields are available in get, list --filter, and export, but they are not written back into source files. Path-derived fields require file-backed records and therefore cannot be used with inline data.
Add description anywhere you need extra context. Entities accept it alongside identifier, and each field definition supports its own description value.
Inline Data
Inline data is helpful for tiny lookup tables or bootstrapping a demo without creating additional files. Define records directly inside the entity specification:
mergeway:
  version: 1

entities:
  Person:
    description: Lightweight profile objects
    identifier: id
    include:
      - data/people/*.yaml
    fields:
      id: string
      name:
        type: string
        required: true
        description: Preferred display name
      age: integer
    data:
      - id: person-1
        name: Alice
        age: 30
      - id: person-2
        name: Bob
        age: 42
Inline records are loaded alongside file-based data. If a record with the same identifier exists both inline and on disk, the file wins. Inline records are read-only at runtime—mergeway-cli data update and mergeway-cli data delete target files only. Types that use identifier: $path cannot declare inline data.
Field Shorthand
When a field only needs a type, map entries can use the compact field: type syntax. These fields default to required: false and behave identically to the expanded form otherwise. Switch to the full mapping whenever you need attributes like required, repeated, or format.
Field Attributes
| Attribute | Example | Notes |
|---|---|---|
type | string, number, boolean, list[string], User, `User | Team` |
required | true / false | Required fields appear in every record. |
repeated | true / false | Indicates an array field. |
description | Service owner team | Optional but recommended. |
enum | [draft, active, retired] | Allowed values. |
default | Any scalar | Value injected when the field is missing. |
JSON Schema Entities
For larger teams it can be convenient to author schemas once and consume them in multiple places. Entities now support a json_schema property that points to an on-disk JSON Schema document (draft 2020-12). The path is resolved relative to the file that declares the entity and needs to live inside the repository—external $ref documents and network lookups are rejected.
When json_schema is present, omit the fields map. Mergeway parses the JSON Schema and converts to its native field definitions:
type: objectbecomes nested field groups, preservingrequiredentries for each level.type: arraysetsrepeated: trueand uses theitemsschema to determine the element type.enum,const, oroneOfblocks translate into Mergeway enums (string values only).$refsegments are resolved within the same JSON Schema file (e.g.,#/$defs/...).- Custom references to other entities use the same
x-reference-typeproperty emitted bymergeway-cli config export. - Reference unions such as
User | Teamare only supported in nativefields:definitions. They are not supported injson_schemaentities. extendsis not supported forjson_schemaentities in the first version of inheritance support.
See examples/json-schema for a runnable workspace that demonstrates this flow end-to-end.
Keep schema files small and focused—one entity per file is the easiest to maintain.
Data Files
Each data file provides the fields required by its entity definition. Declaring a type at the top is optional—the CLI infers it from the entity that referenced the file (through include/selector) and only errors when a conflicting type value is present. Keeping it in the file can still be helpful for humans who open an arbitrary YAML document.
type: Post # optional; falls back to the entity that included this file
id: post-001
title: Launch Day
author: user-alice
body: |
  We are excited to announce the product launch.
You can store one object per file (as above) or provide an items: array to keep several objects together. Mergeway removes any top-level type key before validating the record, so referencing the same file from multiple entities requires the selector approach described below. If a type uses identifier: $path, each file must contain exactly one object; items: arrays are rejected.
Open Knowledge Format (OKF) files
Mergeway also reads Open Knowledge Format (OKF) concept documents from .md and .okf includes. An OKF file must begin with a YAML frontmatter block and its required type property must exactly name the Mergeway entity that includes it. The remaining frontmatter keys become fields, and all Markdown after the closing --- is available as the body field.
---
type: Knowledge
title: Customer Orders
tags: [sales, orders]
---
# Schema

One row per completed customer order.
OKF documents may supply id in frontmatter. If the entity’s identifier field declares a path source, such as source: { path: true }, Mergeway derives id from the file path instead. See examples/okf for a runnable workspace.
For $path identifiers, Mergeway normally derives IDs relative to the workspace root, for example data/notes/alpha.yaml. If an entity include points outside the workspace root, the derived ID may contain ../..., for example ../secondary/products/widget.yaml. Those external-root records can still be listed, fetched, validated, and exported, but create, update, and delete remain limited to files inside the workspace root.
JSONPath selectors let you extract objects from nested structures—handy when you need to read a subset of a larger document. For example, selector: "$.users[*]" walks through the users array in a JSON file and emits one record per element. Mergeway validates that the selector returns objects; any other shape triggers a format error.
Identifier fields accept numeric payloads as well. For example, the following record is valid when the schema marks id as an integer:
id: 42
name: Numeric Identifier
Good Practices
- Prefer references (
type: User) over duplicating identifiers. - Use reference unions sparingly.
type: User | Teamis valid, but validation requires each referenced identifier to resolve in exactly one target set. If the same identifier exists in both sets, validation fails as ambiguous. - Group files in predictable folders (
data/posts/,data/users/, etc.). - Run
mergeway-cli validateafter every change to catch problems immediately.
See examples/reference-union for a minimal runnable workspace that demonstrates User | Team.
See examples/external-root-path for a minimal runnable workspace that demonstrates external-root $path identifiers.
Need more context? Return to the Basic Concepts page for the bigger picture.
How-to Guides
The how-to guides capture focused, task-oriented recipes for Mergeway users. Each guide assumes you already understand the core concepts and need a concrete sequence of steps to accomplish a specific outcome, such as enforcing formatting in CI or wiring Mergeway into deployment automation.
For editor integration, start with Set up mergeway-lsp in VS Code and Neovim.
For MCP client setup, see Use mergeway-mcp with Claude and Codex.
Getting Started with Mergeway CLI Using the Example Repository
Mergeway is a command‑line tool that helps teams describe and validate structured data alongside their code. The mergeway‑example‑repo demonstrates how the CLI can enforce schemas, format YAML/JSON files and generate relationship diagrams using a minimal blog dataset. This guide shows how to set up Mergeway, explore the example repository and add automation so contributors always follow the rules.
1. Cloning the example repository and installing the CLI
Start by cloning the example repository and moving into it:
git clone git@github.com:mergewayhq/mergeway-example-repo.git
cd mergeway-example-repo
The repository’s Getting started section explains two ways to access the CLI:
- Use your own install. Follow the official installation instructions to install
mergeway‑cli. Once installed you can run commands directly in the repo. - Use the provided dev shell. If you use Nix and optionally direnv, you can run
nix developfrom the root. This buildsmergeway‑clifrom source and sets up pre‑commit hooks and validation for you.
With the CLI available, try printing the version and usage information:
mergeway-cli --help    # show usage information
mergeway-cli version   # print the CLI version
2. Understanding the repository structure
The example repository models a simple blog with four entities: User, Tag, Post and Comment. Each entity stores its schema in entities/ and the corresponding records in data/. The top‑level mergeway.yaml file ties everything together and tells Mergeway where to find schemas and data.
Directory overview:
| Folder | Purpose |
|---|---|
entities/ | Contains YAML schemas for each entity (User.yaml, Tag.yaml, Post.yaml, Comment.yaml). |
data/ | Holds YAML or JSON files with records. The subfolders (users/, tags/, posts/, comments/) mirror the entities. |
mergeway.yaml | Top‑level configuration referencing entity schemas and data globs. |
To see the contents of the dataset, you can run:
mergeway-cli entity list          # list all entity types
mergeway-cli entity show User     # inspect the User schema
mergeway-cli list --type Post     # list all post records
mergeway-cli get --type User 1    # fetch a single user by id
mergeway-cli validate             # validate schemas, data and references
These commands read mergeway.yaml, load each entity definition under entities/, and then validate all records under data/. Validation errors are printed in a structured format with the phase (format, schema or references) and the offending file and message.
3. Exploring and extending a workspace
You are not limited to the blog dataset. The Mergeway workspace guide demonstrates how to scaffold a brand‑new workspace, move inline records into separate files and add JSON sources:
- Create a workspace. Make a directory and run
mergeway-cli initto create a newmergeway.yaml. The file starts with an inline entity definition; you can customise it to match your data model. - Use CLI commands. List entities, show schemas, list records and validate the workspace.
- Externalise data. As the table grows, move records into files under
data/and update theincludeglobs inmergeway.yaml. Re‑runmergeway-cli listandmergeway-cli validateto see the effect. - Split schemas and add JSON. Create an
entities/directory and define additional entities (e.g.Product) that pull from JSON via JSONPath selectors. Add the JSON file underdata/and include external schemas using theincludekey inmergeway.yaml. - Fix reference errors. When validation reports missing references (e.g. a
Productrecord refers to a non‑existent category), update the relevant data file and re‑validate to ensure consistency. - Export a snapshot. Use
mergeway-cli export --format json --output <file>to collect the full dataset into a single JSON snapshot.
By following these steps you can evolve the example repository or build your own dataset from scratch while preserving referential integrity.
4. Automating formatting and reviews with GitHub Actions
To keep data formatted and ensure the right people review changes, configure a GitHub Actions workflow and CODEOWNERS. The Set up Mergeway with GitHub Actions guide recommends adding a workflow file called .github/workflows/mergeway-fmt.yml:
name: Mergeway Formatting

on:
  pull_request:
    branches: [main]
    paths:
      - "**/*.yaml"
      - "**/*.yml"
      - mergeway.yaml
  push:
    branches: [main]

jobs:
  mergeway-cli-fmt:
    runs-on: ubuntu-latest
    steps:
      - name: Check out repository
        uses: actions/checkout@v4

      - name: Install Go toolchain
        uses: actions/setup-go@v5
        with:
          go-version-file: go.mod

      - name: Install Mergeway CLI
        run: go install github.com/mergewayhq/mergeway-cli@latest

      - name: Lint Mergeway formatting
        run: mergeway-cli fmt --lint
This workflow runs on every pull request and push to main. It checks out the code, installs Go and Mergeway, then runs mergeway-cli fmt --lint to lint YAML and JSON files. Adjust the paths filters if your data lives outside of YAML files. To ensure only valid PRs are merged, add a CODEOWNERS file that assigns responsibility for specific paths. For example:
# mergeway schema is owned by the Data Platform team
mergeway.yaml @myorg/data-platform

# Data files are split by operational team
data/users/ @myorg/inventory
data/posts/ @myorg/content
GitHub will automatically request reviews from the specified teams when a pull request touches those files. Pinning a version of the CLI (e.g. @v0.11.0) or caching the binary makes CI runs reproducible.
5. Enforcing formatting locally with pre‑commit
Developers can catch formatting issues before pushing by using pre‑commit. The Pre‑commit integration guide outlines the steps:
-
Install pre‑commit once per workstation using
pipx install pre-commit,pip install pre-commitorbrew install pre-commit. -
Add a configuration file
.pre-commit-config.yamlwith a local hook that runsmergeway-cli fmton your data directories:repos: - repo: local hooks: - id: mergeway-fmt name: mergeway fmt entry: mergeway-cli fmt language: system pass_filenames: false files: ^data/(users|tags|posts|comments)/.*\.(ya?ml|json)$The
entryrunsmergeway-cli fmtto rewrite any out‑of‑format records,pass_filenames: falsetells Mergeway to discover files viamergeway.yaml, and thefilesregex limits the hook to data directories. -
Install the hook into your Git repository:
pre-commit install --hook-type pre-commit # optionally also install a pre‑push hook pre-commit install --hook-type pre-push -
Test the hook by running it against all tracked files:
pre-commit run mergeway-fmt --all-files
If the dataset already follows Mergeway’s canonical layout, the hook passes silently; otherwise it rewrites offending files or fails when using --lint mode. This keeps data consistent even before it reaches CI.
6. Next steps
With the example repository and these guides you can experiment with Mergeway, extend the schema to reflect your own domain and automate formatting and validation. Use Mergeway’s other subcommands—such as mergeway-cli gen-erd to generate an entity relationship diagram and mergeway-cli export to snapshot the dataset—to further explore the capabilities. For deeper reference, consult the CLI documentation for commands like mergeway-cli init, mergeway-cli list, mergeway-cli validate and others.
Mergeway encourages teams to treat their data like code: schemas live alongside source files, relationships are validated automatically and collaboration workflows ensure the right reviewers approve every change. Using the example repository as a starting point, you can adapt these patterns to your own projects.
Using JSON Schema & JSONPath in Mergeway
Mergeway’s CLI lets you organize data from multiple sources into well‑typed entities. While simple projects can define fields inline, larger teams often prefer to re‑use existing JSON Schemas or load many records from a single JSON document. This guide shows how to install the CLI, author a JSON Schema‑backed entity, and leverage JSONPath selectors to extract multiple objects from a JSON file.
Prerequisites
Make sure you have the latest Mergeway CLI installed before working with schemas. Review the installation instructions for more details.
Why JSON Schema?
A Mergeway entity typically lists fields manually, but this can become repetitive if you already maintain JSON Schemas elsewhere. Mergeway supports a json_schema property that points at an on‑disk JSON Schema document. The path is resolved relative to the file that declares the entity and must live inside the repository—external $ref documents are disallowed. When json_schema is present you omit the fields map; Mergeway parses the schema and derives fields automatically. Arrays become repeated fields, objects produce nested groups, and enumerations translate into enum types. Keep schema files small and focus on one entity per file.
Example: Customer Entity Backed by JSON Schema
-
Define a JSON Schema. Create
schemas/customer.jsondescribing the shape of a customer record. The sample below shows required fields (id,name,tier), enumerates allowed billing tiers (trial,starter,enterprise), and defines an array ofcontactswith email validation.{ "$schema": "https://json-schema.org/draft/2020-12/schema", "type": "object", "description": "Customer metadata defined with JSON Schema", "required": ["id", "name", "tier"], "properties": { "id": { "type": "string" }, "name": { "type": "string" }, "tier": { "oneOf": [ { "const": "trial" }, { "const": "starter" }, { "const": "enterprise" } ] }, "contacts": { "type": "array", "items": { "type": "object", "required": ["label", "email"], "properties": { "label": { "type": "string" }, "email": { "type": "string", "format": "email" } } } } } } -
Reference the schema in your workspace. Create a
mergeway.yamlthat declares aCustomerentity and points at the schema file. Theincludepattern tells Mergeway where to find customer records.mergeway: version: 1 entities: Customer: description: Customers defined via a JSON Schema file. identifier: id include: - data/customers/*.yaml json_schema: schemas/customer.json -
Add data files. Each YAML file under
data/customers/should match the schema. For example:# data/customers/customer-001.yaml id: cust-001 name: Example Industries tier: enterprise contacts: - label: Primary email: ops@example.com - label: Billing email: finance@example.com -
Validate and explore. Run
mergeway-cli validateto ensure your data conforms to the schema. Usemergeway-cli data list --type Customerto see loaded customers ormergeway-cli gen-erdto visualize relationships.
JSON Schema centralizes validation rules and makes your data contracts explicit. Mergeway automatically converts nested objects into nested fields, sets array fields as repeated, and honours enum constraints. This reduces duplication and lets you re‑use the same schema in other tools.
Loading Multiple Records with JSONPath
Sometimes you want to load many objects from a single JSON file. Instead of splitting the file, you can provide a JSONPath selector in your include mapping. When several objects live in one file, use a selector to extract them.
Users from a JSON Array
-
Prepare the source JSON. Create
data/users.jsoncontaining an array of users:{ "users": [ { "id": "User-001", "name": "Ada" }, { "id": "User-002", "name": "Grace" } ] } -
Define the entity with a JSONPath selector. In
mergeway.yaml, specify thepathandselectorkeys. Theselectoruses JSONPath syntax ($.users[*]) to iterate over the elements of theusersarray.mergeway: version: 1 entities: User: identifier: id fields: id: string name: string include: - path: data/users.json selector: "$.users[*]" -
Load and validate. Run
mergeway-cli validateto confirm the JSONPath extracts objects (non‑objects trigger a format error). Then list users withmergeway-cli data list User.
Tip: Without a selector, Mergeway treats the entire JSON file as a single record or reads the items array if present.
Selectors allow you to re-use existing data files / exports.
Best Practices
- Store each entity’s schema in its own file and keep data organized in predictable folders (e.g.,
data/customers/,data/users/). - Run
mergeway-cli validateafter every change to catch schema or data errors early. - Use enums (
enum/const/oneOf) andformatconstraints in your JSON Schema to enforce consistent values. - Combine JSON Schema and JSONPath when dealing with complex documents—derive field definitions from the schema and extract many objects with selectors.
By integrating JSON Schema and JSONPath into your Mergeway workspace you can model rich data structures, enforce contracts, and scale your repository organization.
Set up mergeway-lsp in VS Code and Neovim
This guide covers the current editor setup paths for mergeway-lsp.
Before You Start
- Put
mergeway-lspon yourPATH, or use an absolute path to the binary. - Open a folder that contains
mergeway.yamlormergeway.yml. - Keep stdout reserved for protocol traffic. Send logs to stderr or a log file instead.
VS Code
Use the extension in vscode/ and follow vscode/README.md, then point it at your local mergeway-lsp binary.
Example workspace settings:
{
  "mergeway.lsp.path": "${workspaceFolder}/bin/mergeway-lsp",
  "mergeway.lsp.trace.server": "off"
}
${workspaceFolder} expands to the first open workspace folder before the extension validates the configured path.
You can also use a plain absolute path instead.
The extension activates only when the opened workspace contains mergeway.yaml or mergeway.yml.
VS Code Generic LSP Client
If you prefer a generic LSP launcher extension, configure it to run mergeway-lsp.
Example settings shape:
{
  "mergeway.server.command": "mergeway-lsp",
  "mergeway.server.args": [
    "--log-file",
    "/tmp/mergeway-lsp.log"
  ],
  "mergeway.server.filetypes": [
    "yaml",
    "json"
  ],
  "mergeway.server.rootPatterns": [
    "mergeway.yaml",
    "mergeway.yml"
  ]
}
Adjust the exact setting names to match the generic LSP client extension you are using. The important pieces are the command, optional debug args, filetypes, and root markers.
Neovim
With nvim-lspconfig, you can register the server directly:
local lspconfig = require("lspconfig")
local util = require("lspconfig.util")

lspconfig.mergeway_lsp = {
  default_config = {
    cmd = { "mergeway-lsp", "--log-file", "/tmp/mergeway-lsp.log" },
    filetypes = { "yaml", "json" },
    root_dir = util.root_pattern("mergeway.yaml", "mergeway.yml"),
    single_file_support = false,
  },
}

lspconfig.mergeway_lsp.setup({})
If you keep the binary outside PATH, replace mergeway-lsp with the absolute path to the executable.
Troubleshooting
- If the server does not start, run
mergeway-lsp --log-stderr --log-level=debugdirectly in a terminal and inspect the error. - If the editor connects but features are missing, confirm the opened folder contains
mergeway.yamlormergeway.yml. - If diagnostics look wrong, compare the same workspace with
mergeway-cli validate. - If you need persistent logs, use
--log-file /tmp/mergeway-lsp.log. - If an editor integration writes logs to stdout, disable that behavior. LSP transport requires stdout to stay protocol-only.
Use mergeway-mcp with Claude and Codex
This guide shows how to launch mergeway-mcp over stdio from a local MCP client.
Before You Start
- Put
mergeway-mcpon yourPATH, or use an absolute path to the binary. - Decide which Mergeway repository root the server should expose.
- Prefer an absolute path for
--rootso the client does not depend on its own working directory. - Keep stdout reserved for MCP protocol traffic. Do not wrap
mergeway-mcpin a script that prints extra output to stdout.
For example, if the repository you want to inspect lives at /abs/path/to/repo, this guide uses:
mergeway-mcp --root /abs/path/to/repo
Add repeated --entity flags if the client should only see specific exact entity names:
mergeway-mcp --root /abs/path/to/repo --entity User --entity Post
Claude
If you use Claude Code, add the server from the CLI:
claude mcp add --transport stdio mergeway -- mergeway-mcp --root /abs/path/to/repo
Run claude mcp list or open /mcp inside Claude Code to confirm that the server is connected.
If you use Claude Desktop, add a stdio server entry to your claude_desktop_config.json:
{
  "mcpServers": {
    "mergeway": {
      "type": "stdio",
      "command": "mergeway-mcp",
      "args": [
        "--root",
        "/abs/path/to/repo"
      ],
      "env": {}
    }
  }
}
If mergeway-mcp is not on PATH, replace command with the full executable path.
After saving the file, restart Claude Desktop so it reloads the MCP configuration.
Codex
You can add the server from the CLI:
codex mcp add mergeway -- mergeway-mcp --root /abs/path/to/repo
To keep the configuration in ~/.codex/config.toml or a trusted project-level .codex/config.toml, use:
[mcp_servers.mergeway]
command = "mergeway-mcp"
args = ["--root", "/abs/path/to/repo"]
If you want to narrow the exposed surface, include entity filters in args:
[mcp_servers.mergeway]
command = "mergeway-mcp"
args = ["--root", "/abs/path/to/repo", "--entity", "User", "--entity", "Post"]
Run codex mcp list to confirm that Codex sees the server.
Example Prompts
Once the client connects, ask for repository inspection tasks such as:
List the Mergeway entities in this repository.Show the schema for the User entity.List the User objects and summarize the identifiers.Export the repository structure and explain the main entity relationships.
Related Pages
- mergeway-mcp Reference — flags, transport options, and tool surface.
- Install Mergeway — installation paths for
mergeway-mcp. - Claude Code MCP docs — Anthropic MCP client documentation.
- Codex manual: Model Context Protocol — official Codex MCP configuration docs.
Set Up Mergeway with GitHub
Goal: wire Mergeway into GitHub so formatting stays consistent and ownership of datasets is clearly distributed across teams.
Throughout this guide we will reference GrainBox Market, a fictional marketplace that stores product data in data/products/ and category lookups in data/categories/. The Data Platform team maintains mergeway.yaml, while Inventory Operations and Category Management own their respective folders.
Prerequisites
- A repository that already contains a valid
mergeway.yamland the files it references. - GitHub Actions enabled for the repository.
- Permission to configure GitHub teams (or at least invite individual maintainers) so CODEOWNERS can route reviews correctly.
1. Add a Mergeway Workflow
Create .github/workflows/mergeway-fmt.yml to ensure every pull request keeps GrainBox data formatted:
name: Mergeway Formatting

on:
  pull_request:
    branches: [main]
    paths:
      - "**/*.yaml"
      - "**/*.yml"
      - mergeway.yaml
  push:
    branches: [main]

jobs:
  mergeway-cli-fmt:
    runs-on: ubuntu-latest
    steps:
      - name: Check out repository
        uses: actions/checkout@v4

      - name: Install Go toolchain
        uses: actions/setup-go@v5
        with:
          go-version-file: go.mod

      - name: Install Mergeway CLI
        run: go install github.com/mergewayhq/mergeway-cli@latest

      - name: Lint Mergeway formatting
        run: mergeway-cli fmt --lint
This job fails fast whenever a record under data/products/ or data/categories/ is out of format, ensuring reviewers only see clean diffs. Adjust the paths filters if your workspace stores data outside YAML.
2. Explain the Failure Mode to Contributors
mergeway-cli fmt --lint prints each offending file, so GrainBox developers fix CI failures locally with mergeway-cli fmt --in-place. Capture that reminder in your pull-request template or CONTRIBUTING guide so the workflow feels helpful rather than mysterious.
3. Assign Ownership with CODEOWNERS
Formatting alone is not enough—you also want the right people reviewing Mergeway changes. GitHub’s CODEOWNERS file routes pull requests to specific teams or individuals based on path globs.
Create .github/CODEOWNERS with entries for both GrainBox teams and any shared files:
# Mergeway schema is owned by Data Platform
mergeway.yaml @grainbox/data-platform

# Data files are split by operational team
data/products/ @grainbox/inventory-ops
data/categories/ @grainbox/category-mgmt
Key considerations:
- Teams need to exist inside your GitHub organization (for example
@org/team-slug). If you don’t have teams yet, either create them under Settings → Teams or list specific people such as@aliceand@bob. - You can mix teams and individuals to cover overlapping areas—for instance, keep
mergeway.yamlowned by@grainbox/data-platformand also list@lead-architectfor extra oversight. - CODEOWNERS applies to all pull requests, so combining it with the workflow guarantees every Mergeway change is reviewed by someone who understands that slice of the dataset.
4. Keep Versions Predictable
GrainBox pins versions for long-lived branches by replacing @latest with a tag (e.g., @v1.2.3) or by caching the binary. Matching versions between local machines and CI prevents “works on my laptop” formatting diffs.
Once the workflow and CODEOWNERS file land in the default branch, any pull request that touches Mergeway files will:
- Trigger the formatting check so contributors fix issues before merging.
- Automatically request reviewers from the right team, ensuring accountability for each dataset.
That combination keeps Mergeway-managed data healthy as your GitHub organization grows.
Enforce Mergeway Formatting with pre-commit
Goal: run mergeway-cli fmt automatically before every commit so contributors push consistently formatted GrainBox Market data.
We will keep using the fictional GrainBox Market repository from the GitHub how-to: schemas live in mergeway.yaml, product data sits under data/products/, and category lookups live in data/categories/.
Prerequisites
- The Mergeway CLI (
mergeway-cli) is already installed on developer machines and in yourPATH. - Python 3.8+ is available (pre-commit ships via
pipx,pip, or Homebrew). - Your repo includes the Mergeway workspace you want to protect.
1. Install pre-commit Locally
Pick the method that matches your tooling:
pipx install pre-commit      # recommended
# or
pip install pre-commit       # inside a virtualenv
# or
brew install pre-commit      # macOS
Developers only need to do this once per workstation.
2. Configure the Hook
Add a .pre-commit-config.yaml file in the repo root (or extend your existing config) with a local hook that invokes mergeway-cli fmt:
repos:
  - repo: local
    hooks:
      - id: mergeway-fmt
        name: mergeway fmt
        entry: mergeway-cli fmt
        language: system
        pass_filenames: false
        files: ^data/(products|categories)/.*\.(ya?ml|json)$
Why these settings?
entry: mergeway-cli fmtrewrites any out-of-format records before the commit proceeds (it defaults to in-place mode).pass_filenames: falselets Mergeway discover files frommergeway.yamlrather than only the files staged by Git—useful when your workspace spans multiple folders.filesnarrows execution to the GrainBox data directories so unrelated commits (docs, code) skip the hook. Adjust the regex for your layout or remove the key to run on everything.
If you prefer CI-style failures, swap --in-place for --lint. The hook will then block the commit and print offending files without mutating them.
3. Install the Git Hook
Tell pre-commit to write the hook into .git/hooks/pre-commit:
pre-commit install --hook-type pre-commit
To cover pushes from automation as well, you may also install it as a pre-push hook:
pre-commit install --hook-type pre-push
Each contributor only needs to run these commands once per clone.
4. Test the Setup
Run the hook against every tracked file to confirm it formats data as expected:
pre-commit run mergeway-fmt --all-files
- If the repo already follows Mergeway’s canonical layout, the command prints
mergeway-fmt..................................Passed. - If output shows
Failed, inspect the listed files, rerunmergeway-cli fmt <file>manually if needed, then stage the changes.
Developers now get immediate feedback before commits ever leave their machines, and CI stays clean because repositories reach GitHub with consistent Mergeway formatting.
Communicate Repository Changes with mergeway-diff
Goal: produce a shareable summary of Mergeway-managed data changes over time by comparing the current repository state to a commit selected with a Git time offset.
We will keep using the fictional GrainBox Market repository from the other guides. Product records live under data/products/, category lookups live under data/categories/, and the Data Platform team wants a weekly update that operations, merchandising, and leadership can all understand without reading raw Git file diffs.
Prerequisites
- The repository is already initialized as a Git repository and contains a valid Mergeway workspace.
mergeway-diffis installed and available on yourPATH.- You know the reporting window you want to communicate, such as the last 7 days.
1. Pick a Baseline Commit from a Time Offset
Use Git to find the most recent commit that existed before your reporting window started:
BASELINE="$(git log -1 --before="7 days ago" --format="%H")"
printf 'Baseline commit: %s\n' "$BASELINE"
git show --stat --oneline --no-patch "$BASELINE"
This command asks Git for the latest commit older than 7 days and stores its full commit identifier in BASELINE. That gives you a stable starting point for a weekly summary without manually searching through history.
If BASELINE is empty, your repository may not have any commits that old yet. In that case, shorten the time window or choose a specific revision manually.
2. Compare the Baseline to the Current Committed State
For a report you want to share broadly, compare two revisions explicitly:
mergeway-diff "$BASELINE" HEAD
This produces a semantic, data-only diff between the baseline commit and the current HEAD commit. Unlike a raw Git diff, mergeway-diff groups changes by Mergeway object identity and field values, so the result is easier to explain to non-specialists.
Example output:
ADDED Product[prod-104]
  at: data/products/prod-104.yaml

MODIFIED Category[cat-bulk]
  description: "Warehouse items" -> "Warehouse and bulk items"

REMOVED Product[prod-017]
  from: data/products/prod-017.yaml
This is usually the right mode for weekly or monthly updates because it ignores local, uncommitted work and reports only the committed state of the repository.
3. Know When to Include the Working Tree
mergeway-diff has three useful snapshot modes:
mergeway-diffcomparesHEADagainst unstaged changes only.mergeway-diff "$BASELINE"compares the baseline revision against your full current working tree, including staged and unstaged changes.mergeway-diff "$BASELINE" HEADcompares two revisions and ignores local worktree noise.
For communication with a broader audience, prefer mergeway-diff "$BASELINE" HEAD. Use mergeway-diff "$BASELINE" only when you intentionally want to preview in-progress changes before they are committed.
4. Validate Before You Share the Diff
Run validation first so your report is based on a clean, parseable dataset:
mergeway-cli validate
mergeway-diff "$BASELINE" HEAD
If the workspace contains invalid YAML, duplicate identifiers, or broken references, fix those issues before publishing the summary. That keeps the diff focused on real data changes instead of repository problems.
5. Capture JSON Output for Automation
If you want to feed the result into a script, dashboard, or release-note generator, use JSON output:
mergeway-diff --format json "$BASELINE" HEAD > weekly-diff.json
This is useful when the Data Platform team wants to post the same weekly change set into Slack, an internal changelog, or a reporting pipeline.
6. Assemble a Shareable Weekly Update
You can combine the time-based baseline, the current commit, and the semantic diff into a short report file:
CURRENT="$(git rev-parse HEAD)"

{
  echo "# GrainBox weekly data update"
  echo
  echo "Baseline: $BASELINE"
  echo "Current:  $CURRENT"
  echo
  mergeway-diff "$BASELINE" HEAD
} > weekly-data-update.md
The resulting file gives stakeholders a compact summary of what changed over the last week without requiring them to inspect every modified YAML or JSON file.
Next Steps
- Review the
mergeway-diffreference for the exact snapshot rules and output modes. - Pair this workflow with
mergeway-cli validatein CI if you want every published change summary to come from a valid repository state. - If you want teams to review the underlying changes before the summary is shared, combine this guide with Set up Mergeway with GitHub Actions.
mergeway-cli Reference
mergeway-cli is the primary workspace-management binary. It handles repository setup, schema inspection, validation, formatting, and object operations.
Use --long-name; single-dash long flags like -root are not supported. Global flags can appear before or after the command name.
| Flag | Description |
|---|---|
--root | Path to the workspace (defaults to .). |
--config | Explicit path to mergeway.yaml (defaults to <root>/mergeway.yaml). |
--format | Output format (yaml or json, default yaml). |
--fail-fast | Stop after the first validation error (where supported). |
--yes | Auto-confirm prompts (useful for delete). |
--verbose | Emit additional logging. |
mergeway-cli Repository Setup
mergeway-cli Schema Utilities
For more information on the schema, please consult the Schema Format
mergeway-cli Object Operations
For the other binaries, see mergeway-diff Reference, mergeway-lsp Reference, and mergeway-mcp Reference. Need a refresher on terminology? See the Basic Concepts page.
mergeway-cli init
Synopsis: Scaffold the directory layout and default configuration for a Mergeway workspace.
Usage
mergeway-cli [global flags] init
mergeway-cli init targets the directory referenced by --root (default .) and does not accept positional arguments. Use mkdir/cd before running the command if you want to initialize a new folder.
Need a walkthrough after initialization? Continue with the Getting Started guide.
Example
mkdir blog-metadata
cd blog-metadata
mergeway-cli init
Output resembles:
Initialized repository at .
mergeway-cli init ensures a starter mergeway.yaml exists in the target directory. Add folders such as entities/ or data/ yourself once the project grows; keeping everything in a single file is perfectly valid. Re-run the command safely—it won’t overwrite existing files.
The default configuration contains:
# mergeway-cli configuration
mergeway:
  version: 1

entities: {}
Related Commands
mergeway-cli validate— run after adding schema and data files.mergeway-cli config lint— verify configuration changes once you editmergeway.yaml.
mergeway-cli validate
Synopsis: Check schemas, records, and references, emitting formatted errors when something is wrong.
Usage
mergeway-cli [global flags] validate [--phase format|schema|references]... [--fail-fast]
| Flag | Description |
|---|---|
--phase | Optional. Repeat to run a subset of phases. By default all phases run (format, schema, then references). |
--fail-fast | Stop after the first error. Defaults to the global --fail-fast flag. |
When you request the references phase, Mergeway automatically includes the schema phase so reference checks have the information they need.
Examples
Run the command from the workspace root (or add --root to point elsewhere).
Validate the current workspace:
mergeway-cli validate
Add --format json when you need machine-readable output.
Output:
status: validation succeeded
Run validation after introducing a breaking schema change:
mergeway-cli validate
Output when the Post schema requires an author but the record is missing it:
- phase: schema
  type: Post
  id: post-001
  file: data/posts/launch.yaml
  message: missing required field "author"
The command writes errors to standard output and still exits with status 0, so automation can check whether any errors were returned.
Related Commands
mergeway-cli config lint— validate configuration without loading data.mergeway-cli list— locate the objects mentioned in validation errors.
mergeway-cli entity list
Synopsis: Show every entity Mergeway discovered from your configuration.
Usage
mergeway-cli [global flags] entity list
No command-specific flags. Add the global --root flag if you need to inspect another workspace.
Example
List entities for the examples/ workspace bundled with the repository:
mergeway-cli --root examples/full entity list
Output:
Comment
Post
Tag
User
Entities are listed alphabetically.
Related Commands
mergeway-cli entity show— inspect an individual schema definition.mergeway-cli config lint— verify the configuration if an entity is missing.
mergeway-cli entity show
Synopsis: Print the normalized schema for a given entity.
Usage
mergeway-cli [global flags] entity show <entity>
No additional flags. Use --format json if you prefer JSON output, and add the global --root flag when working outside the workspace root.
For inherited entities, the output shows the effective flattened schema, including inherited fields. The normalized output also preserves extends metadata so the inheritance chain remains visible.
Example
Show the Post entity in YAML form:
mergeway-cli --root examples/full --format yaml entity show Post
Output (abridged):
name: Post
source: .../examples/full/entities/Post.yaml
identifier:
  field: id
filepatterns:
  - data/posts/*.yaml
fields:
  title:
    type: string
    required: true
  author:
    type: User
    required: true
  body:
    type: string
Related Commands
mergeway-cli entity list— find available entities.mergeway-cli config export— generate a JSON Schema from an entity definition.
mergeway-cli config lint
Synopsis: Validate configuration files (including includes) without touching data.
Usage
mergeway-cli [global flags] config lint
No additional flags.
Example
Run the command from the workspace root (or pass --root):
mergeway-cli config lint
Output:
configuration valid
If the command encounters a problem (for example, an include pattern that matches no files), it prints the error and exits with status 1.
Run this command whenever you edit mergeway.yaml or add new entity definitions to catch syntax mistakes early.
Related Commands
mergeway-cli config export— derive a JSON Schema for a type.mergeway-cli validate— validate both schemas and data.
mergeway-cli config export
Synopsis: Emit a JSON Schema for one of your types.
Usage
mergeway-cli [global flags] config export --type <type>
| Flag | Description |
|---|---|
--type | Required. Type identifier to export. |
Example
Run the command from the workspace root (or pass --root). Export the Post type as JSON Schema:
mergeway-cli --root examples --format json config export --type Post
Output (abridged):
{
  "$schema": "https://json-schema.org/draft/2020-12/schema",
  "properties": {
    "author": {
      "type": "string",
      "x-reference-type": "User"
    },
    "title": {
      "type": "string"
    }
  },
  "required": ["id", "title", "author"],
  "type": "object"
}
Fields that reference other types include the x-reference-type hint.
Reference unions such as User | Team are not exportable as JSON Schema. They are supported only in native Mergeway fields: definitions, so mergeway-cli config export returns an error for those entities.
Validate your workspace (mergeway-cli config lint or mergeway-cli validate) after editing type files to ensure the exported schema stays in sync.
Related Commands
mergeway-cli entity show— view the full Mergeway representation of an entity.mergeway-cli validate— ensure data conforms to the schema you just exported.
mergeway-cli list
Synopsis: List object identifiers for a given type, optionally filtered by a field.
Usage
mergeway-cli [global flags] list --type <type> [--filter key=value]
| Flag | Description |
|---|---|
--type | Required. Type identifier to query. When the type has descendants, the list also includes objects from those descendant types. |
--filter | Optional key=value string used to filter objects before listing their IDs. The comparison is a simple string equality check. Declared read-only fields derived from file paths can also be used here. |
Example
Run the command from the workspace root. If you need to operate on another directory, add the global --root flag.
List all posts in the quickstart workspace:
mergeway-cli list --type Post
Output:
post-001
If an entity uses identifier: $path, the output contains workspace-relative file paths such as data/notes/alpha.yaml. When the entity reads files from outside the workspace root, the identifier may contain ../..., for example ../secondary/products/widget.yaml.
Filter by author:
mergeway-cli list --type Post --filter author=user-alice
Output:
post-001
Filter by a declared path-derived field:
mergeway-cli list --type Page --filter 'section=guides'
For inherited entities, querying the parent includes descendant objects:
mergeway-cli --root examples/inheritance list --type Animal
Output:
dog-1
Related Commands
mergeway-cli get— inspect a specific object.mergeway-cli create— add a new object when an ID is missing.
mergeway-cli files
Synopsis: List included YAML data files, or grouped storage containers, together with their entity types.
Usage
mergeway-cli [global flags] files [--type <type>] [--group]
| Flag | Description |
|---|---|
--type | Optional. Restrict output to one entity type. |
--group | Optional. Collapse one-object-per-file directories to their wildcard path. |
The command only lists YAML-backed files matched by entity include globs. Inline records and JSON files are excluded.
Example
List every included YAML data file:
mergeway-cli files
Output:
- type: Post
  file: data/posts/posts.yaml
- type: Tag
  file: data/tags/tag-product.yaml
Request JSON output for automation:
mergeway-cli --format json files --type Tag
Show storage containers instead of every concrete file:
mergeway-cli files --group
Example output:
- type: Post
  file: data/posts/posts.yaml
- type: User
  file: data/users/*.yaml
Related Commands
mergeway-cli list— list object identifiers for one type.mergeway-cli validate— confirm the listed files still contain valid records.
mergeway-cli get
Synopsis: Print the fields of one object.
Usage
mergeway-cli [global flags] get --type <type> <id>
| Flag | Description |
|---|---|
--type | Required. Type identifier that owns the object. Parent types can also resolve descendant objects. |
<id> | Required positional argument representing the object identifier. For entities that use identifier: $path, this is the relative file path ID, which may include ../... for records loaded from outside the workspace root. |
Use --format json if you prefer JSON output.
If the schema declares read-only fields derived from the backing file path, get includes those fields in the output.
Example
Run the command from the workspace root. Use --root if you need to target another workspace.
Fetch the post-001 record as YAML:
mergeway-cli --format yaml get --type Post post-001
Output:
author: user-alice
body: |
  We are excited to announce the product launch.
id: post-001
title: Launch Day
For path-based identifiers, the lookup uses the file path instead:
mergeway-cli --format yaml get --type Note data/notes/alpha.yaml
External-root $path records work the same way:
mergeway-cli --format yaml get --type Product ../secondary/products/widget.yaml
Inherited entities also work through the parent type:
mergeway-cli --root examples/inheritance --format yaml get --type Animal dog-1
Related Commands
mergeway-cli list— discover identifiers before callingget.mergeway-cli update— change object fields.
mergeway-cli create
Synopsis: Create a new object file that conforms to an entity definition.
Usage
mergeway-cli [global flags] create --type <type> [--file path] [--id value]
| Flag | Description |
|---|---|
--type | Required. Type identifier to create. |
--file | Optional path to a YAML/JSON payload. If omitted, data is read from STDIN. |
--id | Optional identifier override for field-based identifiers. Required when the entity uses identifier: $path, in which case the value must be the workspace-relative file path to create. |
Example
Run the command from the workspace root (or pass --root if you are elsewhere). Create a user by piping a YAML document and letting Mergeway write the file under data/users/:
cat <<'PAYLOAD' > user.yaml
name: Bob Example
PAYLOAD

mergeway-cli create --type User --file user.yaml --id user-bob
Output:
User user-bob created
The command writes data/users/user-bob.yaml with the provided fields. Remove the temporary user.yaml file afterward and run mergeway-cli validate to confirm the new object passes checks.
When an entity uses identifier: $path, pass the target file path with --id, for example --id data/notes/alpha.yaml. Mergeway uses that workspace-relative path as the object ID and does not persist a $path field into the file.
create only writes inside the workspace root. If a type loads records from an external path such as ../secondary/products/*.yaml, you can still list, get, validate, and export those records, but create will reject IDs that point outside the workspace root.
Related Commands
mergeway-cli update— modify an existing object.mergeway-cli delete— remove an object.
mergeway-cli update
Synopsis: Modify an existing object. You can replace the object entirely or merge in a subset of fields.
Usage
mergeway-cli [global flags] update --type <type> --id <id> [--file path] [--merge]
| Flag | Description |
|---|---|
--type | Required. Type identifier. |
--id | Required. Object identifier to update. For entities that use identifier: $path, this is the workspace-relative file path. |
--file | Optional path to a YAML/JSON payload (defaults to STDIN). |
--merge | Merge fields into the existing object instead of replacing it. |
Example
Run the command from the workspace root (or add --root to target another workspace). Update a post title by merging in a tiny payload:
cat <<'PAYLOAD' > post-update.yaml
title: Launch Day (Updated)
PAYLOAD

mergeway-cli update --type Post --id post-001 --file post-update.yaml --merge
Output:
Post post-001 updated
Run mergeway-cli validate after significant updates to confirm references still resolve. Without --merge, the payload replaces the entire object.
For entities that use identifier: $path, pass the workspace-relative file path to --id, for example mergeway-cli update --type Note --id data/notes/alpha.yaml --file note.yaml --merge.
If the resolved record lives outside the workspace root, update rejects it. External-root $path records are intentionally read-only through the CLI even though they can still be listed, fetched, validated, and exported.
Related Commands
mergeway-cli create— add new objects.mergeway-cli delete— remove objects that are no longer needed.
mergeway-cli delete
Synopsis: Remove an object file from the workspace.
Usage
mergeway-cli [global flags] delete --type <type> <id>
| Flag | Description |
|---|---|
--type | Required. Type identifier. |
<id> | Required positional argument identifying the object to delete. For entities that use identifier: $path, this is the workspace-relative file path. |
The command prompts for confirmation unless you pass the global --yes flag.
Global flags (like --yes or --root) can appear before or after the command name.
Example
Run the command from the workspace root (or add --root to target another workspace). Delete a user without prompting:
mergeway-cli --yes delete --type User user-bob
Output:
User user-bob deleted
For path-based identifiers, delete by file path:
mergeway-cli --yes delete --type Note data/notes/alpha.yaml
Like create and update, delete only operates on files inside the workspace root. If a $path record comes from an external include such as ../secondary/products/widget.yaml, you can inspect and export it, but delete will reject that identifier.
Related Commands
mergeway-cli list— confirm an object’s identifier before deleting.mergeway-cli create— recreate an object if you delete the wrong one.
mergeway-cli gen-erd
Generates an Entity Relationship Diagram (ERD) of your data model.
mergeway-cli gen-erd --path <output-file>
This command inspects your configuration and generates a visual representation of your entities and their relationships. It relies on Graphviz (specifically the dot command) to produce the output image.
Arguments
| Argument | Description |
|---|---|
--path | Required. The path where the generated image will be saved. The file extension determines the output format (e.g., .png, .svg). |
Examples
Generate a PNG image of your schema:
mergeway-cli gen-erd --path schema.png
Generate an SVG:
mergeway-cli gen-erd --path schema.svg
Example output, based on the full example:
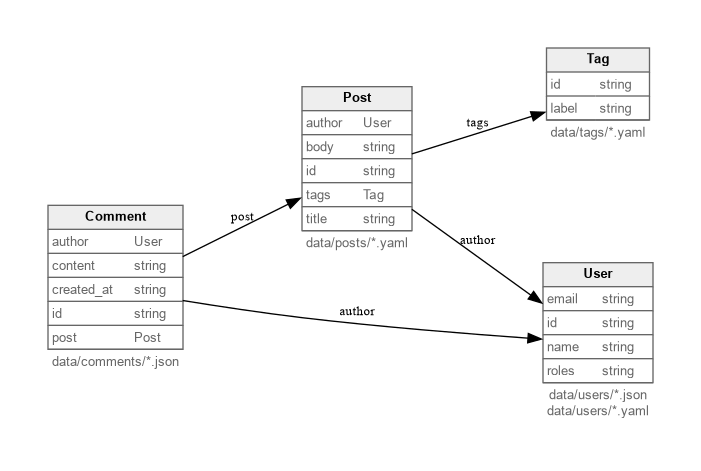
Requirements
The dot executable from Graphviz needs to be installed and available in your system’s PATH.
mergeway-cli export
Synopsis: Export repository objects into a single JSON or YAML document.
Usage
mergeway-cli [global flags] export [--output <path>] [entity...]
| Flag | Description |
|---|---|
--output | Optional path to write the exported document. Defaults to STDOUT. |
entity... | Optional list of type names to include. Omitting the list exports every entity defined in the workspace. |
The export format matches the global --format flag (yaml by default).
Examples
Export every entity in the repository as YAML to the terminal:
mergeway-cli export
Export only the User and Post entities as JSON into a file:
mergeway-cli --format json export --output snapshot.json User Post
Each top-level key in the output map is the entity name; the value is an array of records sorted by ID.
If the schema declares read-only fields derived from the backing file path, those fields appear in the exported payload.
Entities that use identifier: $path can also be exported when their include paths point outside the workspace root. In that case the record IDs and any declared path-derived fields still resolve from those external file paths, including ../... when needed.
Related Commands
mergeway-cli list— inspect available identifiers before exporting.mergeway-cli get— fetch a single object instead of the full dataset.
mergeway-cli version
Synopsis: Display the CLI build metadata (semantic version, commit, build date).
Usage
mergeway-cli [global flags] version
No additional flags.
This command does not touch workspace files; global flags like --root are ignored.
Example
mergeway-cli --format json version
Output:
{
  "version": "0.10.0",
  "commit": "a713be5",
  "buildDate": "2025-10-22T18:25:03Z"
}
Values change with each build; use the command to confirm which binary produced a validation report or data change.
Related Commands
mergeway-cli validate— include the CLI version in validation artifacts for traceability.
mergeway-diff Reference
Synopsis: Compare Mergeway-managed data between logical repository snapshots.
Usage
mergeway-diff [flags]
mergeway-diff [flags] <left>
mergeway-diff [flags] <left> <right>
mergeway-diff --format json [<left>] [<right>]
mergeway-diff is a standalone binary. It does not accept mergeway-cli subcommands.
Flags
| Flag | Description |
|---|---|
--root | Path to the workspace (defaults to .). |
--config | Explicit path to mergeway.yaml (defaults to <root>/mergeway.yaml). |
--format | Output format (yaml or json, default yaml). |
This command is a data-only diff. It compares Mergeway-managed records across the repository and excludes configuration entirely.
Snapshot interpretation:
mergeway-diffcomparesHEADdata against current working tree data using unstaged changes only.mergeway-diff <left>compares<left>against the current working tree state including unstaged changes.mergeway-diff <left> <right>compares<left>against<right>.
Passing more than two positional arguments is an error.
Examples
Compare the current HEAD data against unstaged local changes:
mergeway-diff
Compare an earlier revision against the full current working tree:
mergeway-diff HEAD~1
Emit machine-readable output for automation:
mergeway-diff --format json HEAD~1 HEAD
Notes
- The command reports semantic record changes, not path-based Git file diffs.
- Output is intentionally simple for now and may be refined in a later phase.
mergeway-diff <left>includes both staged and unstaged working tree changes on the right-hand side.mergeway-diff <left> <right>compares two explicit revisions and ignores local working tree noise.
Related Commands
mergeway-cli export— inspect repository data in a serialized form.mergeway-cli validate— validate the current repository state before comparing revisions.
mergeway-lsp Reference
Synopsis: Run the Mergeway Language Server Protocol server over stdio.
Usage
mergeway-lsp [flags]
mergeway-lsp is a standalone binary. It does not read mergeway-cli global flags such as --root or --format.
Flags
| Flag | Description |
|---|---|
--log-file | Write server logs to the given file path. |
--log-level | Set the log level: debug, info, warn, or error. |
--log-stderr | Write server logs to stderr instead of discarding them. |
If you omit all logging flags, the server stays quiet and reserves stdout for JSON-RPC traffic.
Examples
Start the server and wait for framed LSP messages on stdin:
mergeway-lsp
Enable debug logging on stderr while testing a client manually:
mergeway-lsp --log-stderr --log-level=debug
Write logs to a file instead of stderr:
mergeway-lsp --log-file /tmp/mergeway-lsp.log --log-level=debug
Environment Variables
The server accepts environment-variable equivalents for its logging settings:
MERGEWAY_LSP_LOG_FILE=/tmp/mergeway-lsp.logMERGEWAY_LSP_LOG_LEVEL=debugMERGEWAY_LSP_LOG_STDERR=1
Command-line flags take precedence over environment variables when both are set.
Notes
- Keep stdout protocol-only. Human-readable output on stdout will break editor integration.
- In normal use, your editor launches
mergeway-lspfor you rather than you starting it by hand. - The server discovers Mergeway roots from the files the editor opens and uses the same validation core as
mergeway-cli validate.
Related Pages
- Run mergeway-lsp manually — startup basics and current capabilities.
- Set up mergeway-lsp in VS Code and Neovim — editor wiring examples.
mergeway-cli validate— compare editor diagnostics with CLI validation output.
mergeway-mcp Reference
Synopsis: Run the Mergeway read-only MCP server for repository inspection.
Usage
mergeway-mcp [flags]
mergeway-mcp is a standalone binary. It does not run through mergeway-cli, and it does not expose any mutation workflow.
Flags
| Flag | Description |
|---|---|
--root | Root folder of the Mergeway repository (defaults to .). |
--transport | MCP transport: stdio or http (defaults to stdio). |
--http-listen | Listen address for HTTP transport (defaults to 127.0.0.1:8080). |
--http-base-path | Base path for HTTP transport (defaults to /). Only valid with --transport=http. |
--entity | Allow only the named exact entity. Repeat the flag to build an allow-list. |
Behavior
- The server is read-only. It exposes repository inspection tools and does not support create, update, or delete operations.
--entityuses exact entity names. AllowingAnimaldoes not implicitly exposeDog.- Repository state reloads on each request, so changes made after server startup become visible on later calls.
- In
stdiomode, keep stdout protocol-only. Any extra text written to stdout will break the MCP session.
Examples
Start the default stdio server rooted at the current repository:
mergeway-mcp
Point the server at a different repository root:
mergeway-mcp --root examples/full
Expose only the User and Post entities to the client:
mergeway-mcp --root examples/full --entity User --entity Post
Serve the MCP endpoint over HTTP on the default local address:
mergeway-mcp --root examples/full --transport=http
Serve HTTP from a custom mount path:
mergeway-mcp --root examples/full --transport=http --http-listen 127.0.0.1:9090 --http-base-path /mcp
Tool Surface
The initial tool set is intentionally narrow and read-only:
entity_listentity_showobject_listobject_getrepository_exportfiles_list
Clients should treat these tool names and their structured responses as the supported inspection surface.
Notes
- Use
stdiofor MCP clients that launchmergeway-mcpas a subprocess. - Use
httpwhen the client expects a streamable HTTP endpoint. - Bad flag combinations fail before the server starts. For example,
--http-listenand--http-base-pathrequire--transport=http.
Related Pages
- Install Mergeway — release, Go, and source installation paths.
- Use mergeway-mcp with Claude and Codex — stdio client setup examples.
- mergeway-cli Reference — repository management and CRUD commands.
- mergeway-lsp Reference — compare the MCP server with the editor-facing LSP binary.